

Zymtrace is building the AI infrastructure optimisation platform for the GPU era, giving engineering teams continuous, production-grade visibility into their GPU clusters and the tools to automatically fix what they find. 6 Degrees Capital is happy to support the team in a round led by Venture Guides and alongside Mango Capital, Fly Ventures and a group of exceptional strategic angels.
The AI infrastructure boom
Zymtrace sits at the intersection of two defining trends of our era. The first is the extraordinary scale of investment flowing into AI compute. Institutions like Brookfield estimate that more than $7 trillion will be spent on AI-related infrastructure over the next decade, the majority of it directed at GPU servers, the engines that power the training and deployment of AI models.
The global GPU market is expected to reach $326 billion by 2036, growing at over 40% per year. It is one of the fastest-expanding markets in the world, and supply is still struggling to keep up with demand.
There is a growing urgency around efficiency. Despite the enormous investment, most of the compute being bought is not being used well. Industry consensus points to average GPU utilisation rates of just 35–40%, meaning roughly two-thirds of some of the world’s most expensive hardware sits idle at any given moment. Inefficient code, memory stalls, and poor CPU-to-GPU coordination result in wasted cycles, slower training, and inflated inference costs.
The result is a paradox: the industry is simultaneously starved for compute and underutilising existing resources. Closing that gap could unlock billions of dollars in value, and it requires a new generation of tooling.
Flying blind inside the GPU cluster
Understanding why compute is being wasted requires visibility into what is actually happening inside the stack. The dominant observability platforms, Datadog, Grafana, Splunk were built for a different era. Designed to monitor traditional CPU-based applications, they collect high-level metrics but treat GPUs as black boxes. They can tell you that utilisation is at 40%. They cannot tell you why; which lines of code are causing stalls, which memory access patterns are creating bottlenecks, or what it is costing.
When performance problems do arise, diagnosing them demands highly specialised expertise and days or weeks of manual investigation across fragmented tools. Many organisations default to the costly stopgap of buying more GPUs. But the bottleneck is rarely the hardware, it is the code that runs on it.
This is compounded by a scarcity of talent. Performance tuning across CPU-GPU stacks is one of the most specialised skills in software engineering, and almost all of the engineers who can do it are being recruited by NVIDIA, Meta, Google, and the major AI labs. Without automated tooling, fixing bottlenecks remains slow, expensive, and dependent on expertise most organisations cannot hire.
A continuous profiling platform, built for GPUs
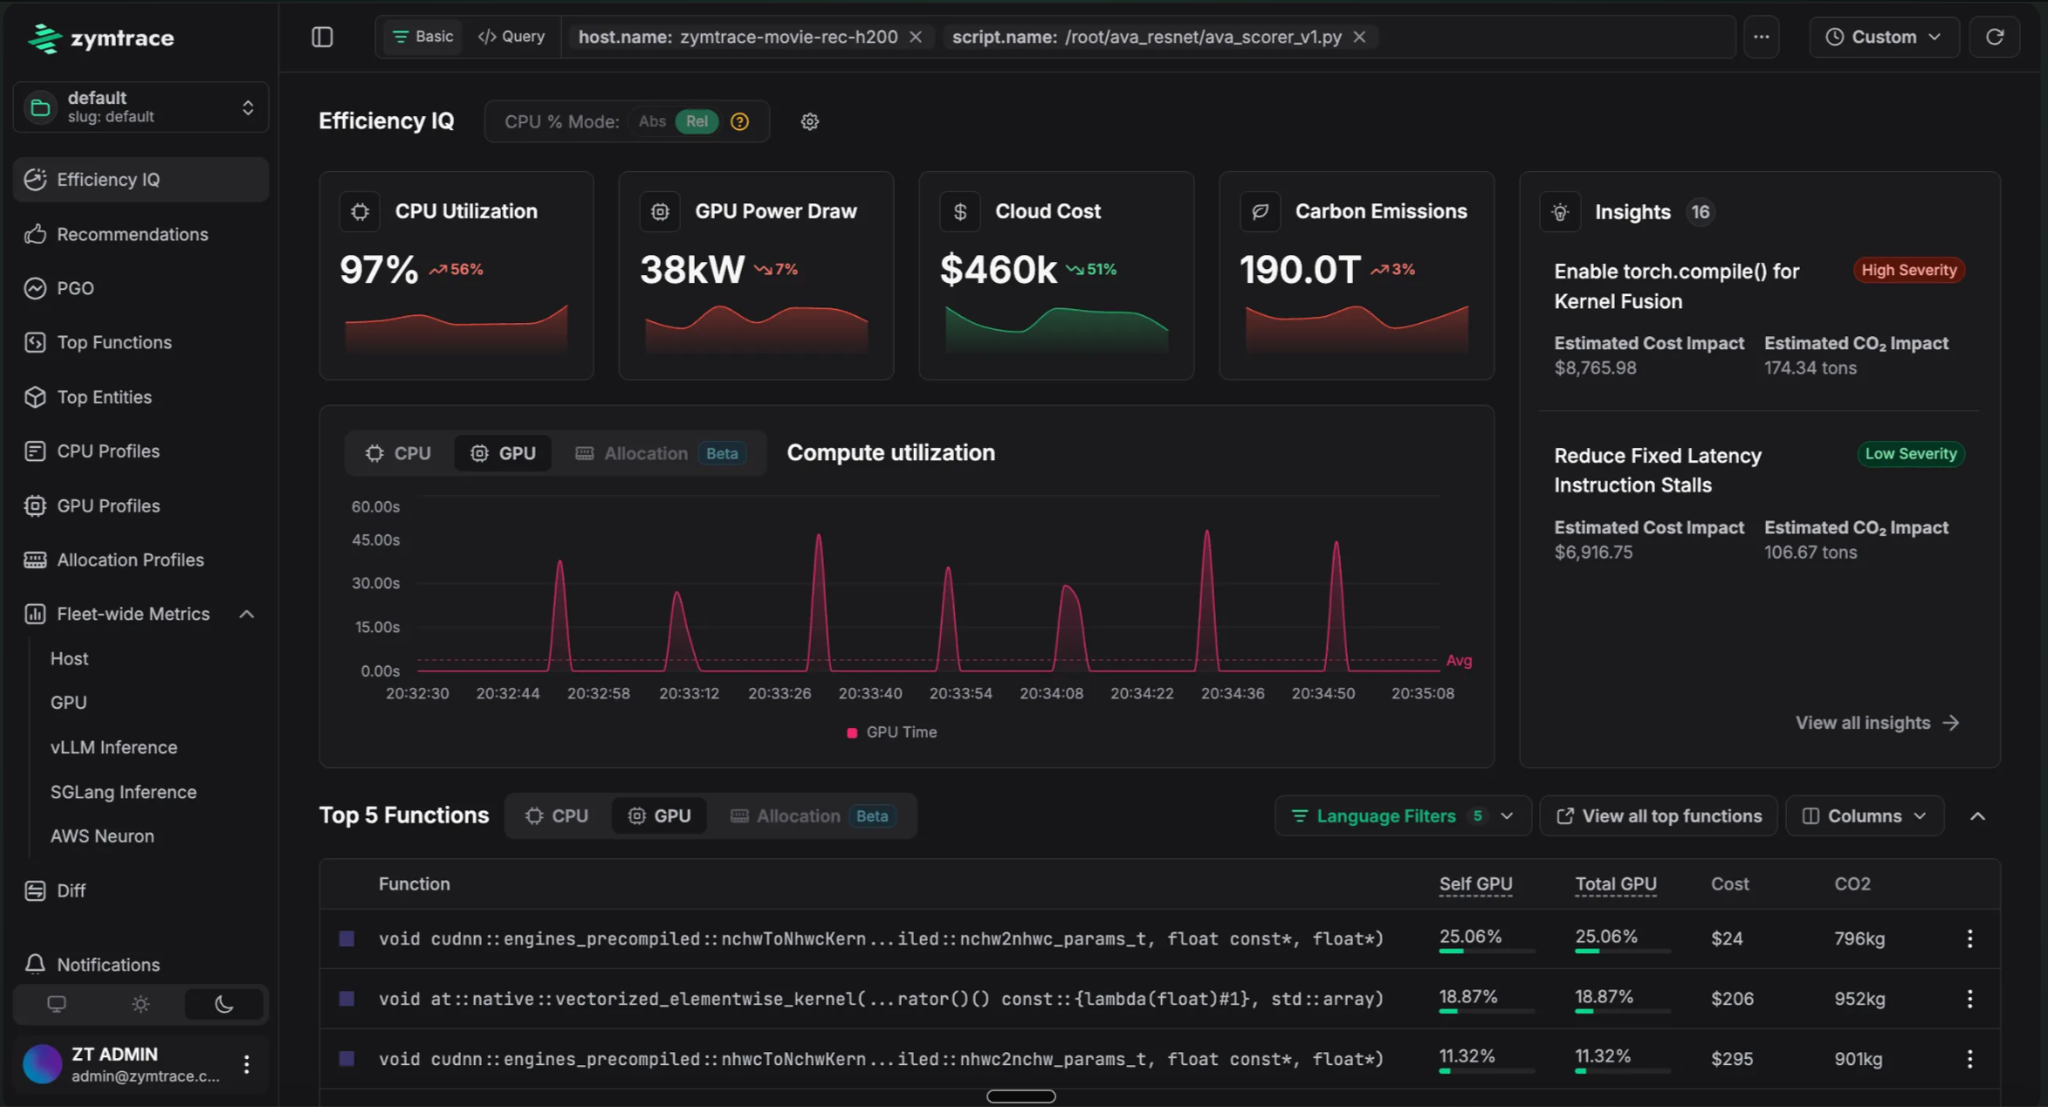
Zymtrace continuously profiles GPU and CPU workloads across distributed systems, correlating cluster-level activity down to individual lines of code. Engineers can trace GPU kernel stalls, memory bottlenecks, and scheduling inefficiencies back to specific CUDA kernels, Python functions, and C++ routines, without any code changes required.
The mechanism that makes this possible is eBPF, a technology that enables safe, low-overhead observation of system behaviour at the kernel level without modifying the applications being observed.
Zymtrace’s founders pioneered, open-sourced, and donated the eBPF CPU profiling agent to the OpenTelemetry project while at Elastic. That technology is now used in production at Cisco, Datadog, Grafana, IBM, and others. At Zymtrace, the same engineering approach is being brought to GPUs.
A critical technical differentiator is that Zymtrace’s eBPF agent can profile without requiring debug symbols or frame pointers, something most competitors cannot achieve. This matters enormously in practice: production environments rarely have debug symbols available. Zymtrace therefore delivers rich, actionable insight not just during development, but in live infrastructure at scale.
Once a bottleneck is identified, the platform goes further than surfacing data. It generates actionable optimisation recommendations with estimated cost and performance impact. Through its Profile Guided AI Optimization approach, Zymtrace completes the full agentic loop autonomously, from detecting a GPU bottleneck to opening a pull request with the fix. With MCP integration, this plugs directly into existing engineering pipelines, cutting what once took weeks of manual investigation down to minutes.
Founders
Israel Ogbole (CEO) has spent more than a decade at the frontier of observability and cloud infrastructure. At Elastic, he led the development of the eBPF CPU profiler now used across the industry. Before that, he was at Cisco AppDynamics and a production engineer at Microsoft. Israel arrives not as someone adjacent to this problem, but as someone who has been building its foundational technology for years.
Joel Höner (CTO) is a reverse-engineering and low-level programming expert with over a decade of experience at the boundary between software and silicon. He co-authored the Zydis x86 disassembler used by Firefox and WebKit, and maintains the eBPF profiling agent within OpenTelemetry. Joel and Israel built the core technology that underpins this category. They are now commercialising it.
The company is advised by Thomas Dullien, founder of Zynamics and Optimyze (acquired by Elastic), and Asaf Ezra, co-founder of Intel’s Granulate — advisors with direct operational relevance to what Zymtrace is building.
Traction
For an early-stage company, Zymtrace has assembled a remarkably credible set of customer relationships. Large enterprises and financial institutions with some of the most demanding GPU infrastructure in the world are working with Zymtrace, with several more progressing through technical evaluation and procurement.
Why Zymtrace
Observability is the second-largest data infrastructure spend category in the enterprise after cloud. The incumbents, Datadog, Splunk et al. are billion-dollar businesses. But they were built for CPU workloads and fall short as GPU infrastructure scales. Enterprise dissatisfaction with legacy vendors is high, and the structural shift toward AI infrastructure is creating a genuine opening for a new class of platform.
Zymtrace’s pricing scales naturally with the size of a customer’s compute fleet, and the addressable market is growing faster than almost any other category in enterprise software.
Looking further ahead, as AI labs and chip start-ups build custom inference hardware to reduce their dependence on NVIDIA, the need for a unified observability layer across heterogeneous chip architectures becomes acute. Zymtrace is positioned to build for that; a hardware-neutral platform that works across NVIDIA, AMD, TPUs, and next-generation silicon. The founders have a credible basis to pursue this: they built the cross-platform profiling standard that the industry already relies on.